Research lab · Self-deployed frontier models
Frontier models. Your hardware.
Make self-deploying open-source models cheaper, easier and faster. We choose, adapt and deploy the model around your workload and the cards you can afford.
For product teams using paid model APIs in production, operators running agents around the clock, and companies whose data must stay on premises. For teams already running open models or preparing to deploy them on their own hardware or cloud account.
What are frontier models? A term for models considered among the most capable. Their fit for your task still needs testing. A guide to the terms used here.
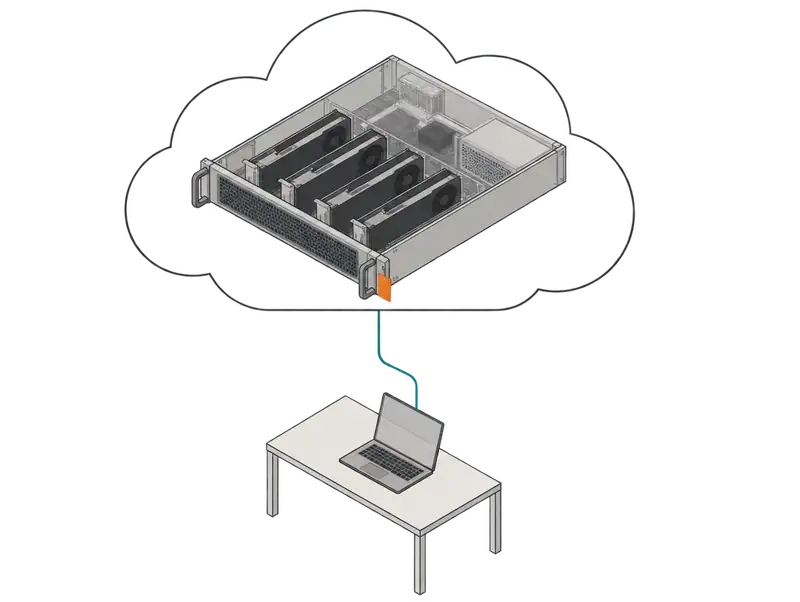
It runs on a computer you own.
Choose the work you need
Start with the decision or build in front of you.
Model deployment & optimization
Fit the model and serving engine to hardware within your budget.
- Installed configuration
- Measurements
- Operating instructions
- Measure
- Adapt
- Install
Model & hardware assessment
Know what to run before you buy hardware.
- Candidate comparison
- Workload baseline
- Cost recommendation
Fine-tuning & evaluation
Test the quality gap, then train where the evidence supports it.
- Evaluation set
- Candidate comparison
- Deployment artifacts
Research you can inspect
The lab researches engines, quantization, pruning, speculative decoding and Hebrew models. Published experiments describe their own setup and limits; they are not promises about your deployment.
Browse the researchShared scale from zero; units: %
Recorded code sequences
Inspect the data table
| Condition | BF16 | NVFP4 |
|---|---|---|
| Recorded code sequences | 62.61 % | 61.32 % |
Quantization reduces the memory needed to store the model’s numbers and can make it possible to run on a card with less memory. This chart tests an acceleration method that proposes a token, a unit of text, before the main model verifies it. First-token agreement was similar with and without quantization in this experiment. This does not measure answer quality. Learn about tokens and speculative decoding.
What fits your hardware?
A model fitting in memory is only the start. The choice also depends on answer quality, request size, simultaneous work and the cost of operating the system.
Inputs
- Task and examples
- Quality checks
- Expected load
- Hardware and budget
Decision factors
- Model choice
- Memory and execution
- Response time
- Total operating cost
Output
- A measured recommendation and a deployment scope.
Does the move pay?
We compare your API bill with the full cost of running a suitable open model on your hardware or cloud account. The proposal covers adaptation, deployment, infrastructure, operation and support, with setup and running costs shown separately. It shows whether the move saves money. You control the deployment, data and logs.
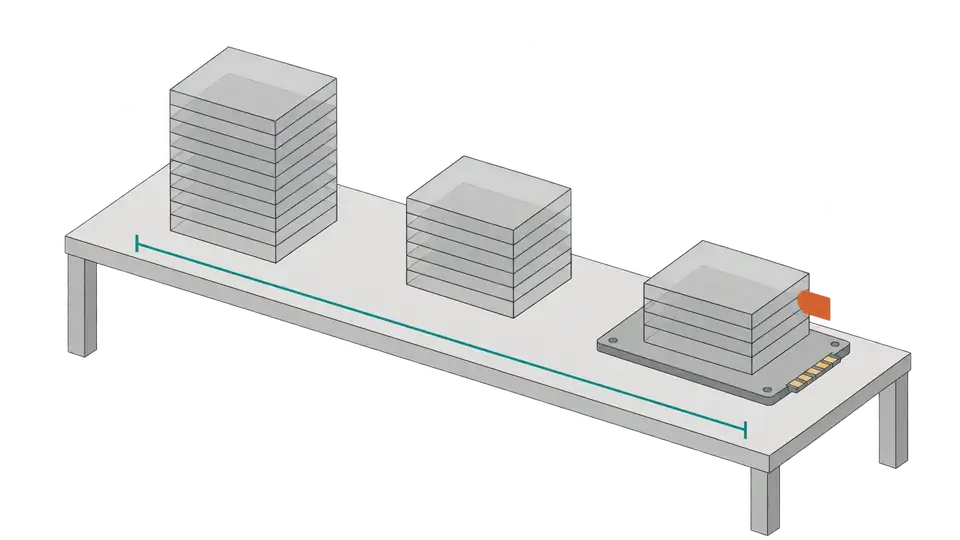
From examples to a system you can run
Each stage has a clear purpose, from the first comparison to handover and continuing support.
Choose
Define the task and compare model and hardware options.
Adapt
Test fine-tuning, architecture and engine changes where they address a measured gap.
Deploy
Install, test and document the system on your hardware or cloud account.
Support
Support coverage and handover are set out in your proposal.
Our engineers keep supporting the systems they build, under agreed terms. About the lab →
Bring the workload and the budget.
We will work out what to measure and what to build.